
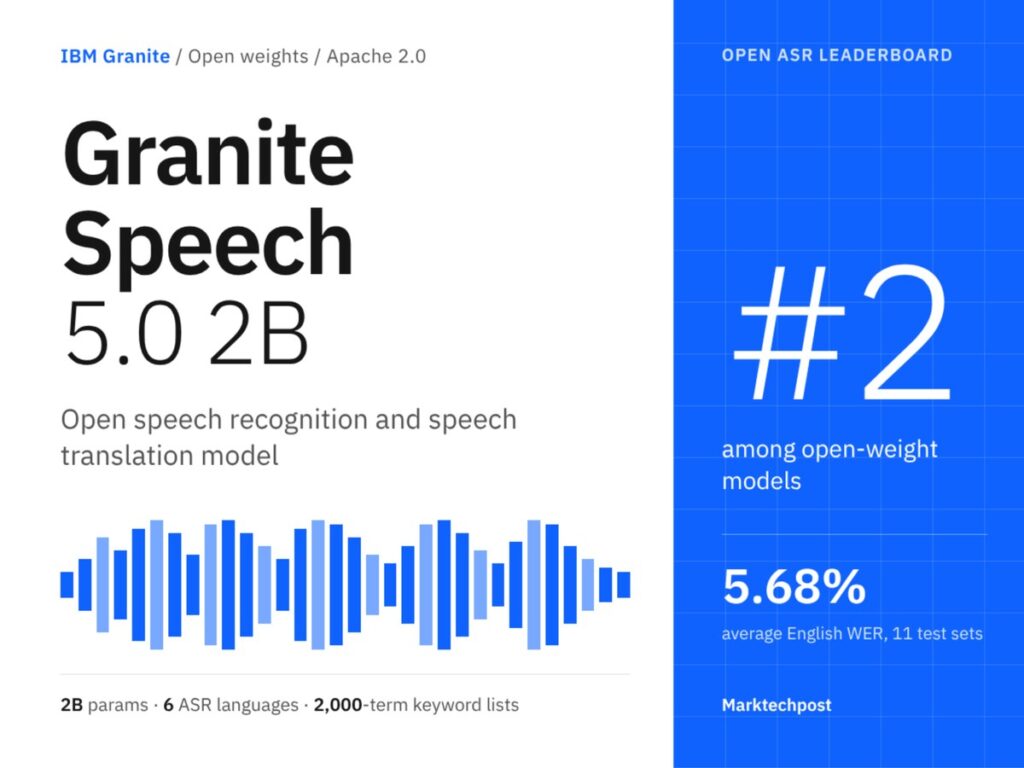
IBM has released Granite Speech 5.0, an open family of speech models covering transcription, translation, and multi-speaker recordings — all under the Apache 2.0 license. The headline addition is granite-speech-5.0-2b, a 2-billion-parameter model for high-accuracy multilingual transcription and translation.
The new 2B model transcribes English, French, German, Spanish, Portuguese, and Japanese, and translates to and from English across those languages (plus English into Italian and Mandarin). IBM says it trained on 390,000 hours of public audio plus synthetic data, with better handling of noise, echo, and distant microphones. On the Open ASR Leaderboard’s public English short-form sets, IBM reports an average word error rate of 5.06%, which it describes as second among open-weight models. The release also refreshes two existing models: the 470M Turbo CTC for ultra-fast on-device transcription, and the 4.1 2B Plus for meetings with improved speaker attribution and timestamps.
All three run on GPU via Transformers or vLLM, on Apple Silicon via mlx-audio, and locally on CPU via llama.cpp — meaning speech AI can stay fully on-premise with no per-token API fees. For alternatives in this space, see our coverage of Speechmatics, Deepgram, AssemblyAI, and Gladia, and our Otter.ai vs Fireflies comparison for meeting-transcription workflows.
Source: MarkTechPost


